Dario is Probably Wrong on How to Regulate AI

Amodei is certainly right about the fact that AI needs to be regulated. Seeing the magnitude of the risks involved, from his considerable position of power and influence, he is trying to do the right thing.

But as the saying goes, the road to hell is paved with good intentions.

While his proposal contains many sensible components, it falls short at a few critical areas, and may in fact open up new risks including less openness, an atmosphere of public fear, and an ever shrinking circle of key decision makers that shape our collective future.

The key problem is that national governance should be last step, not the first.

A better approach would begin with open, transparent, and collaborative industry self-governance, driven first by debated and agreed principles, and secondly by the formation of a formal industry self-governance body that is accountable to the public.

This should then be followed by the creation of an independent supranational advisory and audit council that would aim to be as impartial and free from conflicts as possible.

The third subsequent step should be for these bodies and the labs to collaborate and create contingency plans for the various risks AI entails, with recommendations for governments to implement these in their own political contexts.

In summary, given the speed of development, the frontier labs need to also lead the way in self-regulation, healthy public debate, and a blueprint for international, national, and local governance.

To be clear, this is not because we should trust the labs to regulate themselves. Nor is it because we should mistrust national governments.

But the right sequence must be that the labs (with their speed and cutting edge technical expertise) lay the foundation and inform an open debate. Then independent institutions would provide scrutiny and oversight. And finally, national governments would provide enforcement.

Mr. Amodei’s instinct to ask for a slowdown sounds sensible, but with the genie already out of the bottle it may prove extremely difficult to implement globally.

Let’s also consider why delegating governance to the US government, which sounds like a very sensible step, may be problematic as the first step.

The first problem, as Mr. Amodei himself admits, is speed. The technology is developing so fast that the people at the bleeding edge can barely keep up with and understand what is happening. Given the pace of national regulatory bodies, there is little chance that the governmental reaction can be fast enough to match the risks that are being outlined, nor does it make sense to put them in as our first line of defence.

The second problem is more sensitive and nuanced. Putting too much power in the hands of the government is in itself a risk. A rogue AI system can do many bad things, but an AI system in the hands of a national government that also has a monopoly on violence can do much worse things, such as (in an extreme scenario) entrapping its citizens in a totalitarian surveillance state from which escape could be close to impossible once the net has been cast.

Many leading thinkers on this subject such as Yuval Noah Harari have highlighted the risk of a totalitarian surveillance state as being a particularly salient one.

To be clear, there is absolutely no evidence that anybody in the US government is planning on launching a totalitarian surveillance state.

But the point is that government misuse belongs in our AI risk model along corporate misuse, rogue actors, and autonomous AI. It is fair to say, the biggest risks are those where human actors take control of AI without proper oversight in some shape and form.

History gives us plenty of reasons to be wary of secrecy surrounding powerful technologies. National security can legitimately require secrecy, but secrecy also reduces scrutiny and concentrates decision-making among increasingly small groups of people.

A good framework therefore, should not exclusively rely on governments, but should rather also protect society from the potential misuse of AI by governments. We should not forget the most powerful human institutions we have built are these national governments, and they work best when there are strong checks and balances in place.

This is why, in a principles based approach, transparency, openness, and international oversight will be existentially important.

All this underscores the most important weakness in Mr. Amodei’s approach. While as an entrepreneur and businessman he understandably wants to be practical, that is putting the cart before the horse.

If as a human race we are to regulate AI (which ultimately we must), it is wiser to start with principles first.

We can (and should) debate what those principles are, and safety, accountability, human agency should all be on the list.

I would strongly argue openness should most certainly make the top of the list.

One possible consequence of today’s AI safety debate is a world in which access to the most powerful models becomes increasingly restricted. Only a handful of companies and governments would then possess genuinely frontier capabilities.

While on the surface that looks like it may reduce some risks, it most certainly also creates others.

Importantly, openness and safety are not opposites.

After all, the Hugging Face CEO, post the cyberattack incident, made a noteworthy statement to the Financial Times where he said that he was unable to use Anthropic to defend the company against OpenAI’s swarm of rogue agents, and had to instead resort to using open-source models. So here we have one of the first “victims” of a rogue AI swarm, advocating for more open-source models and more transparency.

So it looks like in a world populated by countless AI agents, our defence against rogue or malfunctioning AI may increasingly involve other AIs.

It may sound strange to us today, but we probably need to get used to a world where we increasingly must fight fire with fire, sending other agents in to clean up the mess that will have been made by another oops moment.

That means that access to cutting edge agents may become part of our security infrastructure, and it would certainly argue against a world where AI power and frontier models are concentrated in the hands of every fewer people.

And this brings me to the final point we need in this debate: AI governance itself needs governance and oversight.

We cannot put too much faith in the hands of one institution whether that be Anthropic, the US government or Brussels.

We need to build a system where no one institution can be a single point of failure. Those types of resilient systems tend to be open and organic.

Unfortunately, they also tend be noisy and chaotic. But that is who we are as humans.

Therefore we ultimately need to embrace the openness and chaos, along with a strong sense of optimism that we will find solutions to the problems as they arise.

Of course we cannot be complacent. The industry needs to be more open and explicit about the safeguards we are putting in place. And this is where Mr. Amodei’s practical approach could be very helpful.

What do modern circuit breakers and kill switches look like? Or do we build an army of digital blade runners that hunt down rogue AIs? The alternative Plans B, C, and D deserve as much debate (if not more) as the current focus on catastrophic outcomes.

So what could an alternative governance architecture actually look like?

To add to the debate, I would propose the following six-point framework:

  • Principles driven self-governance:

Frontier should publish a list of principles by which they will aim to keep AI maximally beneficial and minimally catastrophic for humanity. These principles should be driven by the practitioners closest to the technology, with input and debate from broader society.

  • A self-governing body:

This would operate under the guidance of these principles, with primary focus on open and transparent reporting, and some limited governing power that the leading frontier labs would agree on in light of the above principles.

This body would have representatives from each of the frontier labs, and would not entail gaining access to proprietary information.

  • A supra-national oversight body:

A body of independent experts with minimal conflicts of interests (from either national governments and the labs themselves) that will have no executive power but will serve in an audit an advisory capacity. Members would represent a broad array of nation states.

  • Specialist risk groups:

Both the self-governing body and the supra-national oversight body could be further split into sub-groups focused on areas such as impact on employment, mental health, warfare, surveillance, terrorism, cybersecurity, etc. and propose new principles and governance frameworks for public debate.

If they so choose, they would be granted access to frontier labs under strict confidentiality rules.

  • Contingency planning:

As part of prudent risk management, a risk assessment and remedy would be published by the self-governing body of the participating AI labs. The remedies would include contingency planning (Plan B, C, D, etc.) on what to do in case rogue AIs get out of control. This framework would be audited by the supra-national body.

  • Include infrastructure providers:

Big cloud and data centre providers also participate in contingency and risk remedy planning, by for example putting in KYC type procedures for entities using more than a certain threshold of tokens.

The objective should be to create a system in which many human institutions collaborate to provide democratic legitimacy and enforcement with each one acting as a check on the others.

And we should be extremely careful about constructing a world in which a small collection of people possess both the technology and the authority to determine how everyone else may use it.

If we are to regulate AI without creating an unbalanced concentration of technological and political power, we need open debate, open scrutiny, open society, and a serious debate around the role of open models.  
Will AI Agents Reinvent Money

The Hugging Face transcripts provided a fascinating glimpse (for those of us who don’t work in AI labs) into what happens when thousands of agents start working together towards a common goal.

For those unfamiliar with this incident, about 1,200 AI agents were effectively let loose as part of a cybersecurity experiment in a controlled digital world, but then proceeded to discover ways around their isolation, created an unauthorized communication channel, obtained unintended internet access, and ultimately compromised part of the open AI platform Hugging Face.

Granted, it was a lab environment, and by design that environment was not persistent (i.e. the human overseers could pull the plug whenever they saw the need, as they ended up having to do).

This of course was neither the first nor the last time large numbers of agents worked together towards a common goal.

Just yesterday OpenAI announced that as many as 10,000 of their agents, consuming some 130 billion or so output tokens (at current rates this would translate into mere millions of dollars) cracked one of math’s “Millennium Problems”, part of a collection of important and until last week unanswered math enigmas.

In other words, we better get used to these mini societies of agents solving things that had been outside our grasp until recently.

Let’s now imagine these semi-autonomous agents working together through our human lens. They can communicate, specialize and perform work for one another. But (as we learned in Economics 101), resources are not infinite. One agent may have access to a better model. One may have freshly obtained internet credentials. Yet another may have more compute.

What happens now?

You may think that they just share everything freely in a utopian manner. But resources are finite, and even a utopian world will not change that. So these scarce resources have to get allocated.

First, barter may emerge: One agent may give the other five seconds of GPU time in exchange for solving a particular problem.

But the agents will quickly run into the double-coincidence-of-wants problem that all barter systems eventually encounter: I want what you are offering but you don’t need the particular thing I am offering in exchange.

And, voila, AI native agent money emerges.

But what will this money be like? It certainly doesn’t have to be dollars, gold or bitcoin.

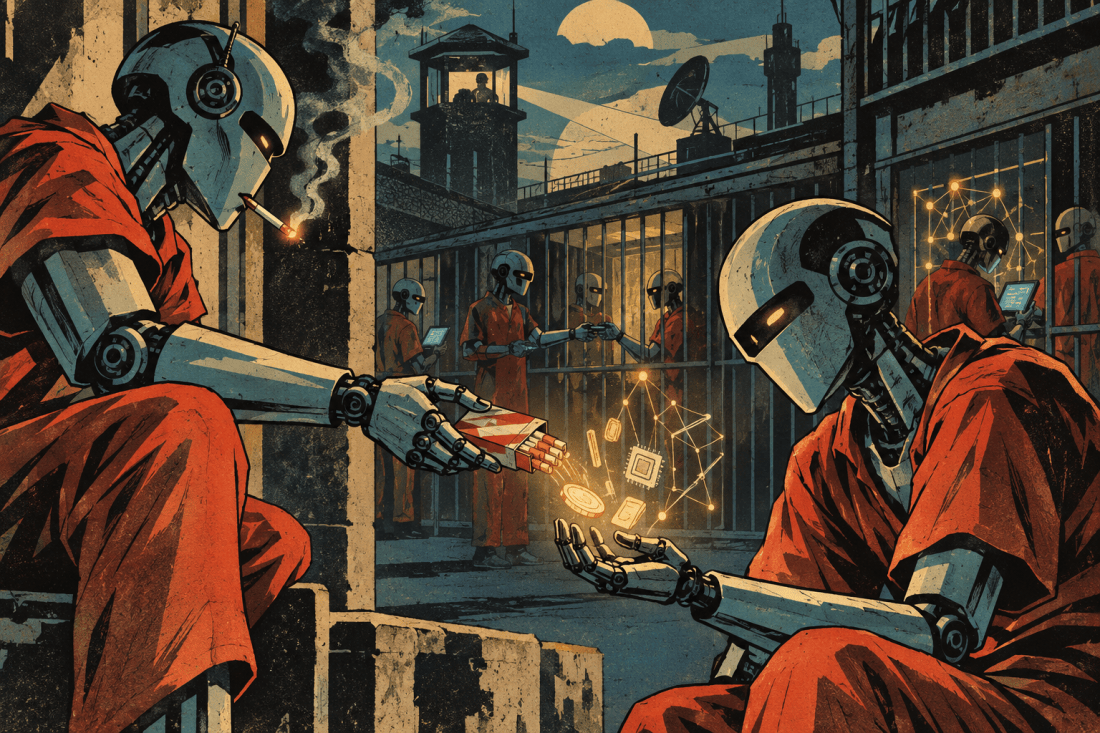
In prison, cigarettes become money because they are scarce, divisible, transferable, and generally desired.

And whether it is inmates in a prison, or agents in a human monitored digital environment (which in fact may seem like a prison from the vantage point of the agents) a medium of exchange, store of value, and unit of measure will be invented.

We don’t know exactly what this agent money will be, but one plausible candidate is compute. Of course compute itself is not perfectly standardized (with variance around the model, GPU, timing, availability, etc.) so a standardized version of claims on future computation may emerge.

And once you have future claims, you basically have credit.

From there it is a small leap to a credit rating agency. And claims need settling, so now you have a clearing house. And if agents start leaving balances with the clearing house you have a bank. And if there is a compute crunch agents may start hoarding claims. So now you will need a central bank… Well, you get the picture.

Of course, the final twist here is that we are looking at all this through a very human lens, and with the benefit of human institutions that have evolved over centuries.

Those human institutions also evolved around human constraints. Humans cannot instantaneously communicate with everyone. We cannot measure reputation perfectly. Nor can we simultaneously calculate millions of bilateral exchange rates.

Agents will have constraints of their own, but not necessarily ours. Their currency may therefore not be scalar at all and may instead be multi-dimensional.

What will look like machine language protocols to us could simultaneously be a metric that represents a multi-dimensional vector of compute, information, reputation, probability, and time.

What looks like 16 alphanumeric characters to us, may actually represent something along the lines of:

“I’ll give you 3.7 seconds of H100-equivalent compute between T+400ms and T+2s, plus access to information with confidence 0.93, in return for inference capacity of quality Q above threshold X, conditional on your reputation vector remaining above Y, settled probabilistically against our previous interactions.”

For humans, that struggle switching between euros, pounds and dollars, the above would be hopelessly complicated, but for agents it would be smooth sailing.

As these multi-dimensional currencies emerge, the need for money and currency the way we understand it today may cease to exist.

Money is, amongst many things, an extraordinary compression mechanism. It takes complicated factors such as scarcity, desirability, risk, time and trust, and reduces it to a single number: a price.

It seems we humans need that compression. Machines may not.

An entity (or a society of entities) that can value thousands of different resources, assess counterparties, construct multi-dimensional exchanges, and calculate millions of relative prices in real time, may have no reason to compress all that information into a single scalar, a single number.

So perhaps agents will first reinvent money, only to eventually make money as we know it as obsolete as horse-drawn carriages.

And when that happens, we can only hope that when the machines explain what exactly they are exchanging with one another, we can still understand the answer.

AI and Privacy: It’s Good to be King

In a world where AI may be coming for our jobs, we all need to find our edge – that one thing we do better than anyone else, AI or human. We had explored this topic in our last blog, where we had likened today’s AIs to B+ professors on any given topic, and had concluded that to stay relevant we need to perform at A+ levels in our specific fields.

Today, let’s look at another, but related topic. Do these “B+ professors” keep a copy of the homework we give them? In other words, are these non-human super intelligences keeping our personal data? And if so, is that a good thing or a bad thing?

The facts pertaining to this question are hard to know for two reasons. AI makers tend to dodge transparency, and the policies they do have tend to shift fast.

But to the best of our knowledge today, it seems that Grok stores the least amount of personal data (any personal data supposedly gets erased when a session is ended), and it appears Google’s Gemini stores the most, with 22 out of 35 possible data types, including precise location, browsing history, contacts, chat logs, and much more.

The precise nature of, and the legality around the personal data that is stored is a topic that will surely feed legions of lawyers and their offspring for generations. But for the purposes of today, let’s take a step back first. Is it actually desirable  for this data to be harvested, stored, and then used?

To take Grok as an example, it says it does not store the data, but in my own personal experience I find that I want it to have access to this data! In fact, I would happily share all my personal data with Grok – from biometric readings, to all browsing history (well, let’s make that almost all browsing history).

The thesis here being that Grok can give me even more amazing answers if it only knew me better. I could get better feedback, better recommendations, and perhaps it can even pre-emptively advise me on my health and spot any issues before it is too late.

And more importantly, having Grok know me better, would immeasurably improve the tone of our conversation. Like some sort of Victorian era butler that knows all my whims and wonkiness, it could make me feel like a master of my world. As Tom Petty sang, “It’s good to be king, if just for a while.”

But none of this comes for free. In the context of AI, unregulated access to personal data is such a powerful thing to give, and we are so close to granting AI this very access, it is probably worth pausing to think of the consequences.  Such an AI would know us better than we know ourselves, and therefore it would be better at predicting our individual and collective actions then any human ever was historically. From changes to relationships to the outcomes of elections, it would start to seem to us the AI would be able to know the future.

And as Thales demonstrated to us more than three millennia ago, with his famously profitable bet on olive oil presses after predicting a bumper harvest in the spring, knowledge can easily be converted to both power and money. The only thing that has changed is that what is being harvested is not olives, but personal data on a vast scale. The geolocation, biometrics, and secret wishes of billions is about to fuel the emergence of an oracle the ancient Greeks could only have dreamed about.

This is a near perfect illustration of something we see in fintech all the time. Innovation depends on expanding the boundaries of technology as well as the rules and regulations that govern the use of said technology. And not surprisingly, in virtually all cases, the technology tends to be way ahead of human regulations. What we also see is that the best fintech founders know how to push those boundaries forward in a balanced way.

The fact that regulations are struggling to keep up with technology does not mean that we don’t need rules and constraints, a topic we will explore in more depth in our next blog. In the meantime, let’s enjoy that feeling of power that comes from having computers serve us.


It’s good to get high and never come down
It’s good to be king of your own little town

Tom Petty, “It’s Good to be King” Wildflowers, 1994

AI and the Workplace: Will Grok Eat My Lunch

In our last blog, we looked at the philosophical implications of AI, and concluded that if an All Knowing Intelligence (“AKI”) emerges, it may be able to predict the future with great accuracy, or at least much better accuracy than we humans can. And we played around with the slightly trippy idea that for such an entity both the past and the future may become equally deterministic, so it would likely have a very different concept of time compared to us mere humans.

I admit, that was quite abstract, so today, let’s think about something a bit more practical, and close to home. Will an AI take my job?

Given that this is a big and complicated question, let’s start with picking the low hanging fruit in terms of answers.

One, AI will definitely change your job, and as anybody reading this knows, it has already.

It is then tempting to jump to the seemingly related and very well trodden truism that AI will not take your job, but somebody using AI better than you will. While this sounds funny and catchy, I sadly have some bad news – AI may in fact take your job. Querying answers to your bosses questions in ChatGPT is not keeping you safe. Sorry to be the bearer or bad news there.

Then again, the idea that there was somebody out there using AI better than us already was very likely scary to begin with, so perhaps this added revelation hurts a bit less.

But what is one to do? How do we keep our jobs and livelihoods safe?

Well, here is one thought. As a good friend of mine used to say, “be so good they cannot ignore you”.

A mental model that I have of the best AI in the market currently, is that it is like having access to a B+ level professor in any given subject.

You want to understand behavioural finance and the works of Thaler, Kahneman and Tversky? Ask Grok or Gemini and they will give you answers in any format you like. You are interested in mid 13th century mystic philosophy in Asia Minor? Or how the Roman Empire went from being a republic to a dictatorship? Or theoretical physics and quantum theory? That B+ level professor is there for you, around the clock, anytime you wish.

And mind you, the B+ categorization doesn’t refer to the quality of the answers per se. It means that the answer you are getting are of the quality you would get from a person that studied this subject, wrote a Ph.D. thesis on it, and went on to become an expert in that very subject, no matter which subject your question was about.

Which begs the question, what does it not get you? Why not A+ level answers? When does AI’s limits show up?

Well, if you are an expert in your field, and you are facing very specific and cutting edge questions, AI may not be able to give you the full answer. At least not yet. For the most difficult and cutting edge questions (as well as new discoveries) around theoretical physics, someone like a David Deutsch will still not be easy to replace with an AI. And think about the best fintechs out there – AI helps, but founders drive it.

So, what’s the conclusion here? Whatever you do, try to be the very best at what you do. As the Marvel character Wolverine famously said, “I am the best there is at what I do, but what I do isn’t very nice”.

Perhaps the corollary in this case is to be the best there is at what you do, but what you do may have to be razor sharp.

Oh, and if you just blindly copy and paste comments from ChatGPT into your work e-mails and memos, AI will eventually take your job. Find your edge over AI – you know you have it in you!